

Financial Data Extraction from 350+ Websites · Data Engineering · Integration & Automation
BlackRock
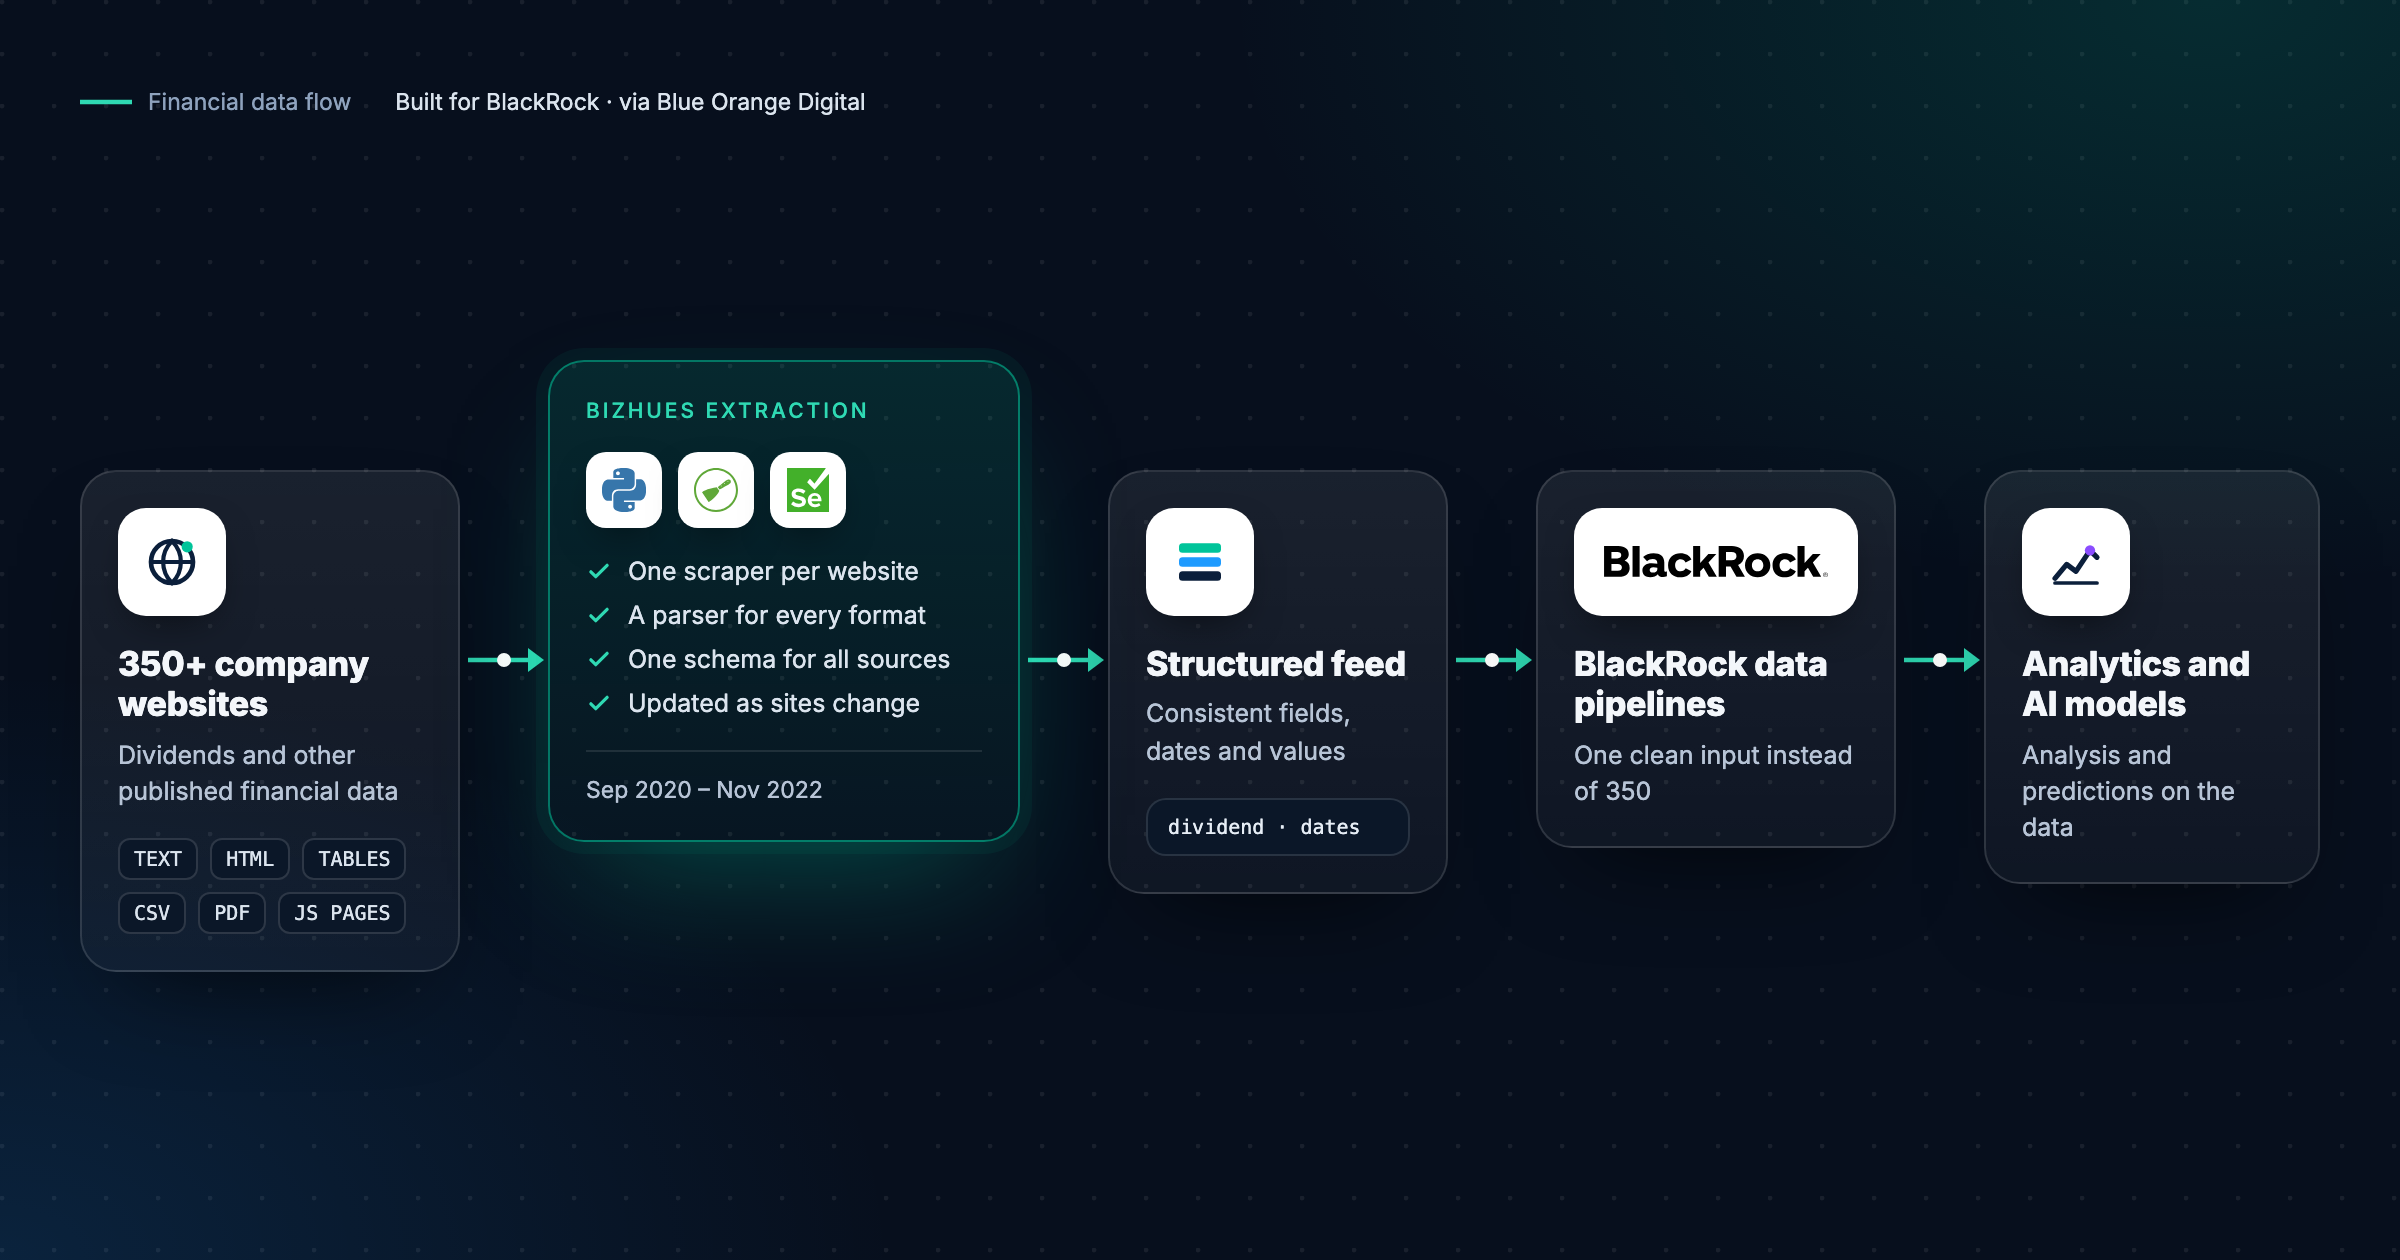
BlackRock, the global investment manager, runs analytics and AI systems that depend on a steady supply of financial data. Working for BlackRock as a delivery partner to Blue Orange Digital, from September 2020 to November 2022, BizHues built the data collection behind part of that supply: extraction from more than 350 company websites, feeding BlackRock's data pipelines.
Built with
- Python
- Scrapy
- BeautifulSoup
- Selenium
- PDF parsing
- CSV processing
- Data normalisation
Expertise
- Large-scale web data extraction
- Multi-format parsing
- Data normalisation
- Data pipelines for analytics and AI
- Financial data
Verticals
- Financial services
- Asset management
- Investment analytics
Companies publish a great deal of financial information themselves: dividend declarations, payment and record dates, and other figures they release to investors. BlackRock wanted that data flowing into the pipelines behind its financial analytics platform and the AI models that analyse it and make predictions. The information is public, but it is not published in any standard way.
Every one of the 350-plus sources was different. Some companies post dividends as text in news releases, some in HTML tables, some as downloadable CSV files, others inside PDF reports or on pages that only load their content with JavaScript. Layouts differed from site to site and changed over time, and none of it was designed to be read by a machine.
For data that feeds investment analytics, partial or misread figures are worse than none. The extraction had to be precise, consistent across every source, and robust enough to keep running as hundreds of independent websites changed.
We treated each website as its own source rather than forcing them through one generic scraper. Every site got a dedicated scraper built for its structure, so a redesign on one company's site affects only that scraper and never holds up the other 350.
Underneath the scrapers sits a parsing layer for each format the data arrives in. Text is read from release copy, HTML tables are read cell by cell, CSV files are downloaded and parsed, PDF reports are opened and their tables and passages extracted, and pages that build their content with JavaScript are loaded in a real browser before anything is read.
Whatever the source and format, every record is normalised into the same structure, with consistent field names, dates and values, so BlackRock's pipelines receive one clean feed rather than 350 different ones. That consistent output is what lets the data go straight into analytics and model inputs without per-source handling downstream.
BlackRock's data pipelines receive financial data from more than 350 company websites as one consistent, structured feed, covering sources that publish in text, HTML tables, CSV files, PDF documents and JavaScript-rendered pages.
That feed supports BlackRock's financial analytics and the AI systems that analyse the data and make predictions from it. Over more than two years of continuous work, the collection grew source by source and was maintained one site at a time as companies changed their websites.
The engagement shows the kind of data engineering BizHues brings to analytics and AI work: getting messy, scattered, real-world data into a form that models and analysts can rely on.
Talk to an engineer
Like what you see?
Tell us about the system you need. We reply with questions and a suggested first step.