

A D2C brand's site crawls on the first evening of its Navratri sale. The next week a scanner flags an old dependency. A month later the database stalls when marketplace orders sync in. Three people fix three things at three different times, and the cache rule added for speed ends up showing one customer another customer's order page.
Speed starts with what the browser downloads
Most slow pages are slow because they send too much. The first pass is the boring version, and it fixes more than anything clever. Split the JavaScript so a page loads only the code it uses. Lazy-load images below the fold. Serve images as WebP or AVIF at the size the layout actually displays.
A product grid that ships twenty full-resolution JPEGs straight from the designer's export is slow in Noida on fibre and unusable in a Tier-2 town on 4G.
Then count the requests a page makes and look hard at the third-party scripts. A tag manager, a chat widget and two analytics pixels can cost more than all of your own code put together. Measure before and after with Lighthouse or WebPageTest on the pages people actually land on, the product page and the checkout, not only the homepage. If you need to agree on what to measure first, start from the metrics that make a website high-performing.
Then the server end
After the browser, look at where the response is produced. A CDN keeps static files and cacheable pages near the visitor. On the server, find the slow queries and add indexes for the filters people actually use, city and category, not the twelve nobody touches. Put Redis in front of data that is read constantly and changes rarely, such as the category tree or the pin code serviceability list.
Write down every cache rule as you add it, with what it covers and what varies by user. You will need that list later in this post.
Security belongs in the design
Security fixes bolted on late tend to be partial. The habits that cover most of what goes wrong are not exotic:
- Serve everything over HTTPS.
- Validate input and use parameterised queries, so a search box cannot become a SQL injection.
- Escape output against XSS, and protect state-changing requests against CSRF.
- Use an established authentication library or service. Writing your own OTP login flow is rarely worth the risk.
- Patch dependencies on a schedule, not when a scanner shouts.
- Log failed logins and odd request patterns, and make sure an alert reaches a person.
The weak spot is almost always the admin area and the internal tools. The public site gets a security review. The operations dashboard, where staff can see every customer's phone number and change prices, gets a password and a hope. Apply the same rules there. Treat every request as untrusted, including the ones from your own frontend, because the frontend is JavaScript running on somebody else's machine.
Scaling means moving work out of the request
A server that does everything inside the request slows down for every user at once. The fix is to ask less of each request.
Run several instances behind a load balancer. Push slow work into background workers through a queue. Order confirmation emails, invoice PDFs, image resizing and analytics events can all wait a few seconds, and the customer sees the order placed before the GST invoice is even rendered. Add read replicas to the database before you think about sharding. Split into separate services only when one part of the system genuinely needs to scale or deploy on its own, which is less often than conference talks suggest.
- 01Visitor
- 02CDNstatic files, cached pages
- 03Appresponse and fragment cache
- 04Queueemails, images, lead routing
Heavy work leaves the request, so the page returns before it finishes.
Where the three collide
Fixes in one area leak into the others, and this is where most of the real incidents come from.
Cache a page that contains account details and one customer sees another's order history. Put a CDN in front of the application and the server now sees the CDN's IP address, so rate limiting based on the client IP stops working and a scraper walks through the whole catalogue. Move a job that carries user data into a background queue and it needs the same access checks as the request that created it, because the worker has no idea who asked. Add three more servers without central logging and an attack can hop between machines for a day before anyone sees the pattern.
- Faster for anonymous visitors
- Fewer database reads
- Logged-in data shared between users
- Stale prices or availability
Cache rules must say what varies by user before anything is cached.
The cache case is the one I keep coming back to in reviews. A page cache set up to survive sale traffic is a good idea. The same cache applied to the account page because someone used a wildcard rule is a data leak waiting for the first logged-in visitor. Checking takes one command per page, in production, not in staging:
curl -sI https://shop.example.com/account/orders | grep -i -E 'cache-control|x-cache|vary'
You want Cache-Control: private or no-store on that response, and no cache hit from the CDN. Anything else goes on the fix list before the sale starts.
How LIWeddings was built for load
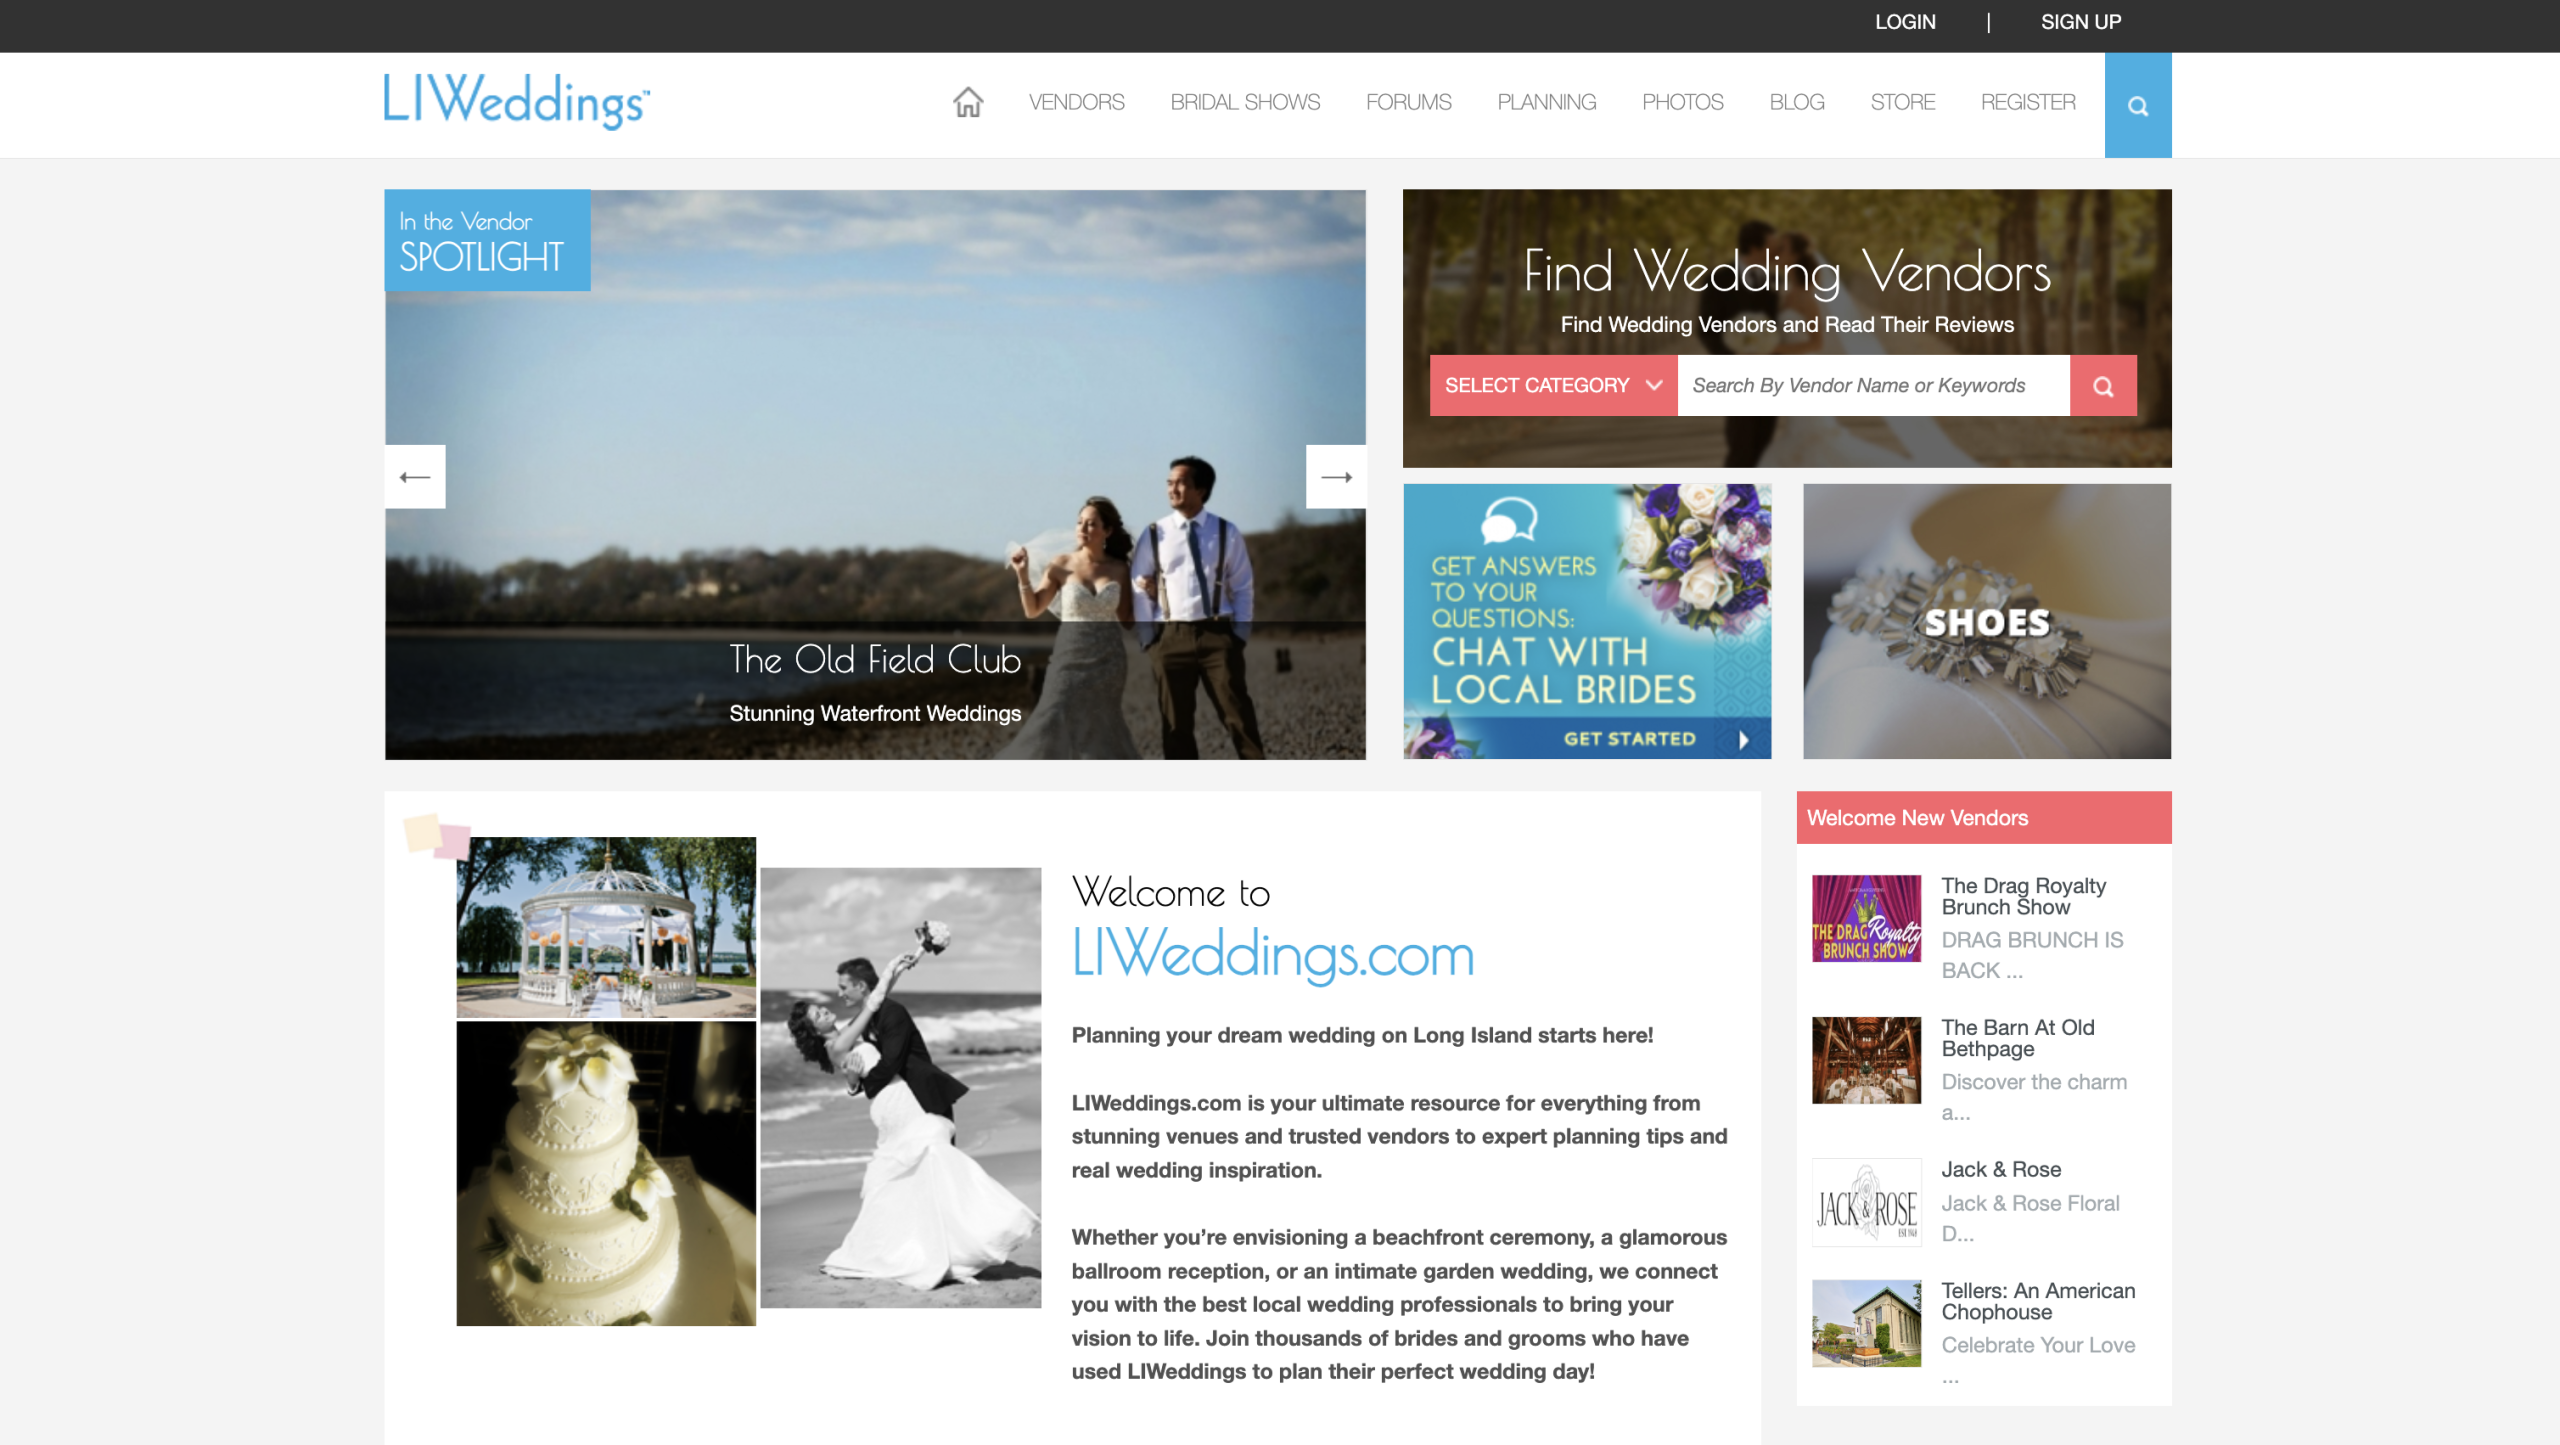
LIWeddings is a Long Island wedding vendor marketplace with forums, rebuilt as a Laravel monolith with MySQL. The documented stack applies several of the techniques above. Blade and Livewire serve interactive pages without a heavy client-side framework. Response and fragment caching and a CloudFront CDN keep pages quick. Redis queues managed by Horizon handle notifications, lead routing and image processing outside the request. Role policies control who can do what, and structured data supports search visibility.
A monolith with good caching and queues is often enough. You do not need microservices to stop a page from waiting on an email.
Checklist before a release
- Run Lighthouse on the three most visited pages. Record the results.
- List every cache rule and what varies by user.
- Check response headers on every logged-in page.
- Confirm slow work runs in a queue, with access checks on the job.
- Check dependencies for known vulnerabilities.
- Send logs from all instances to one place.
Start with the cache rules. They touch speed, security and scale at once, and a wrong one is the hardest kind of bug to explain to a customer. If you are planning a larger rebuild, our web development page covers how we approach it.
From our work
LIWeddings
Planning your dream wedding on Long Island starts here!
Read the project story

